AI Solution Architect • GenAI Engineer • Agentic AI Developer
AI that helps people learn, adopt and perform: designed as a system, not a demo.
I design and ship AI systems end to end: standards-grounded retrieval, evaluation harnesses, guardrails and the change management that gets them adopted. Ten years leading enterprise learning and enablement for utilities, government and education.
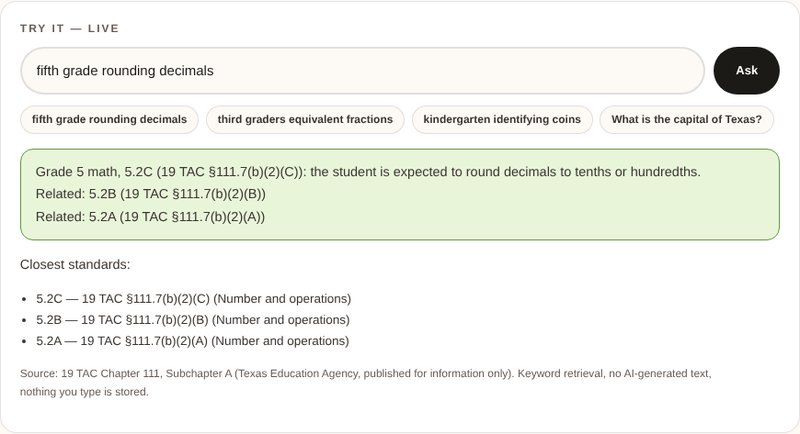
Ask about any K–5 Texas standard: reading, math, science, social studies and more.
Source: Texas Essential Knowledge and Skills, K–5, revised June 2024 (Texas Education Agency, published for information only). Keyword retrieval, no AI-generated text, nothing you type is stored.
6states’ standards crosswalked with AI-assisted analysis
100%first-submission approval, statewide certification program
40%team turnaround gain after introducing AI workflows
Client details are generalized. The tutor’s source is public; other repositories are private.
How I work
Process, setbacks and what I changed
Frame the problemwith teachers, parents and learners
Set constraints firstprivacy, cost, accuracy, review
Write the standard firstrules, then automatic checks
Ship thin, then measuregolden questions, held-out test
Break it on purposeoff-topic, messy input, edge cases
Harden and documentwrite down what is unfinished
What went wrong, and how I fixed it
Standards tutor · evaluationIt answered everything, including “What is the capital of Texas?”
What happened: keyword search always returns something, so the first version gave a confident wrong answer to off-topic questions.
What I changed: I wrote 12 off-topic questions, tuned a decline rule on half and tested it on the half it had never seen. The first rule declined only 2 of 6 held-out off-topic questions. I added a second signal: how many of the question’s words exist anywhere in the standards.
Result: all 6 held-out off-topic questions declined, with 1 of 20 real questions wrongly declined.
Then it got harder: when I loaded all ten subjects, trivia such as “What is the capital of Texas?” matched a social studies standard that mentions a state capital, and the tutor answered it. I recalibrated on the new dev questions, reported the held-out numbers as they came out, and recorded the capital question as a known failure instead of removing it from the tests. A relevance check is the planned fix.
Takeaway: a threshold that looks fine on the data it was tuned on can fail on new questions, and again when the corpus grows. Hold some back and re-measure.
Standards tutor · source dataI could not get the official text, and I would not build on a paraphrase
What happened: automated lookups of the Texas standards were blocked or returned summaries, not the exact wording.
What I changed: I used the official PDF instead. Parsing it exposed line-break artifacts such as “two- dimensional,” which I fixed, then locked the counts into a regression test. When I later loaded ten subjects, I checked the new parser against the old math parse: 287 of 288 records were identical, and the one difference was a double period in TEA’s own file. Every answer cites the rule and notes that the state publishes it for information only.
Takeaway: ground the system in the primary source, and test the data pipeline, not just the model.
Standards tutor · architectureWhere to host it: price versus the visitor’s first impression
What happened: I compared three hosts using their own pricing pages. One has no free tier, one gives about $1 of monthly credit, and the free one goes to sleep after 15 minutes, so the next visitor waits about a minute.
What I changed: I ported the retrieval to TypeScript and ran it as a function on the site’s existing host. The port returns the same top results and the same answer-or-decline decision on all 52 test questions as the Python original.
Takeaway: choose the architecture by what the user experiences and what you already own, then prove the port is equivalent.
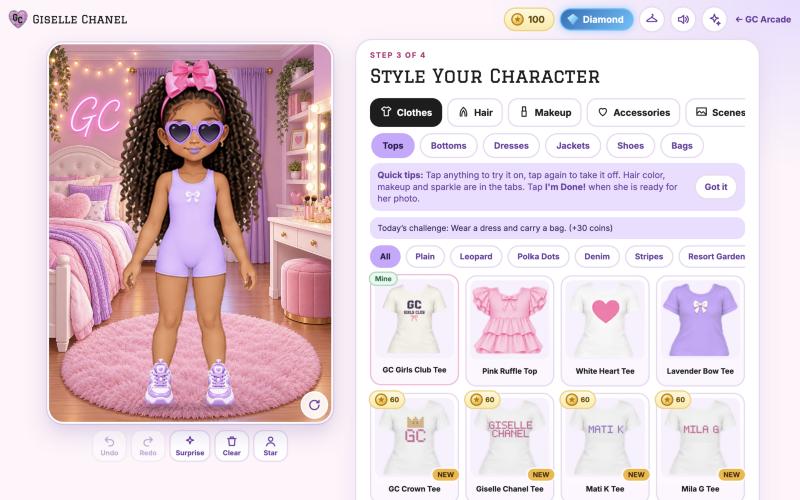
Style Studio 2.0 · product qualityHairstyles that looked fake, shirts that showed skin
What happened: in preview testing, tops and bottoms were mixed up, eyeliner landed over the eyes, skin showed through shirts, lipstick missed the lips, and the hairstyle overlays looked artificial.
What I changed: I fixed the layering and coverage problems one round at a time through preview deploys. I parked the hairstyles until proper hair art exists, instead of shipping something that looked wrong.
Takeaway: cutting a feature is a design decision. A preview build lets a person review before anything goes live.
Assessment content · guardrailsGood-looking quiz questions with hidden patterns
What happened: a review of the library quizzes showed the kind of patterns students learn to game, such as the right answer being the longest choice.
What I changed: I wrote the reviewer’s rules down, then turned them into a validator that fails the site build. It also checks every quoted answer against the source text.
Takeaway: a rule that depends on someone remembering it will be skipped. Automated checks catch patterns, and a person still reads for meaning.
Parent reports · reliability“Every Friday at 5” changes twice a year
What happened: scheduled jobs run on universal time, so a fixed schedule drifts by an hour when the clocks change.
What I changed: the job runs at both possible hours and sends only the run that lands on 5 p.m. Central. It records the week it sent, so a retry can never email a family twice.
Takeaway: design automation so that running it twice is harmless.
Ground answers in a source I can citeDeclining beats guessingMeasure on questions the system has not seenKeep a person in the loop for reviewDesign for the most vulnerable user firstOwn the data path
I started as a classroom teacher and have spent more than ten years building learning for schools, corporations, government agencies and utilities. That taught me what makes a system succeed: clear standards, careful review, and respect for the people who use it.
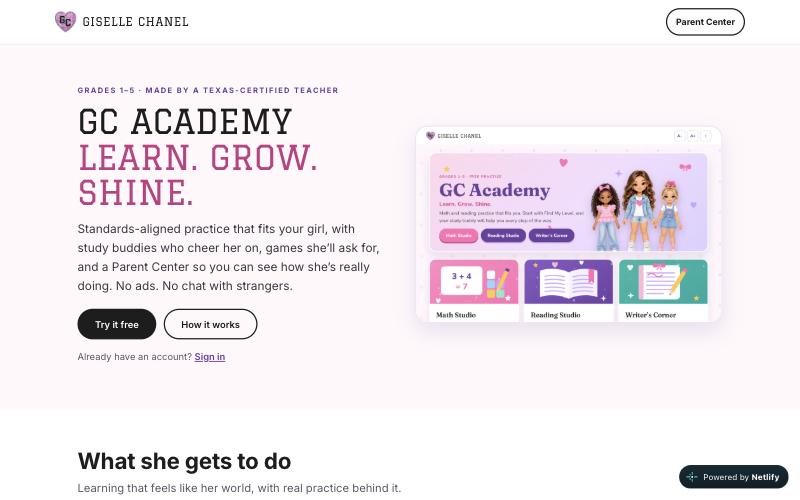
Now I build AI the same way: grounded in sources I can cite, measured before I trust it, and designed for the most vulnerable user first. In my own products, that user is a child.
Texas-certified educatorMBA and M.Ed. in Educational TechnologyFounder, Kemp Advisory GroupExecutive Director (non-voting), Cornerstone Clay CDCEducators Rising 2022: four students recognized nationallyAuthor in progress: AI for Educators
Where I’ve applied AI at work (5 roles)
Aug 2025 – present
Principal Learning Architect
Kairos Worldwide / Kemp Advisory Group
Embed generative AI prompting structures into role-based job-task analyses, so engineering and system specifications become clear instructional objectives for an enterprise software rollout.
Jul 2025 – Apr 2026
Curriculum Strategy Consultant
Accelerate Education
Used AI analysis to build standards crosswalks across six states, and led an economics and financial literacy initiative to state approval with 100% compliance.
Feb 2024 – Jul 2025
Lead Instructional Designer
Hurix Digital
Brought generative AI and large language models into standard content pipelines, deployed AI voiceover platforms, and led a team that improved turnaround efficiency by 40%.
Jul 2023 – Aug 2024
Senior Lead Instructional Designer
Six Red Marbles
Designed a statewide educator certification program that was approved on first submission, and a curriculum redesign that raised exam performance by 30%.
2015 – 2022
District curriculum writer, team lead and teacher
Tyler ISD and Chapel Hill ISD
Wrote and facilitated curriculum for a 17,000-student district, then taught and led the education and training program.